dictatd 2 - the smallest model that works
The plan was simple. Whisper for transcription, a small llama model for grammar. Easy, or so I thought.
Then I loaded gemma 3 4b, quantized, and almost gave up on the spot. A 4b model on a cpu is a turtle in a language race, something like 5 tokens a second. You'd finish speaking your next sentence before it finished fixing the last one.
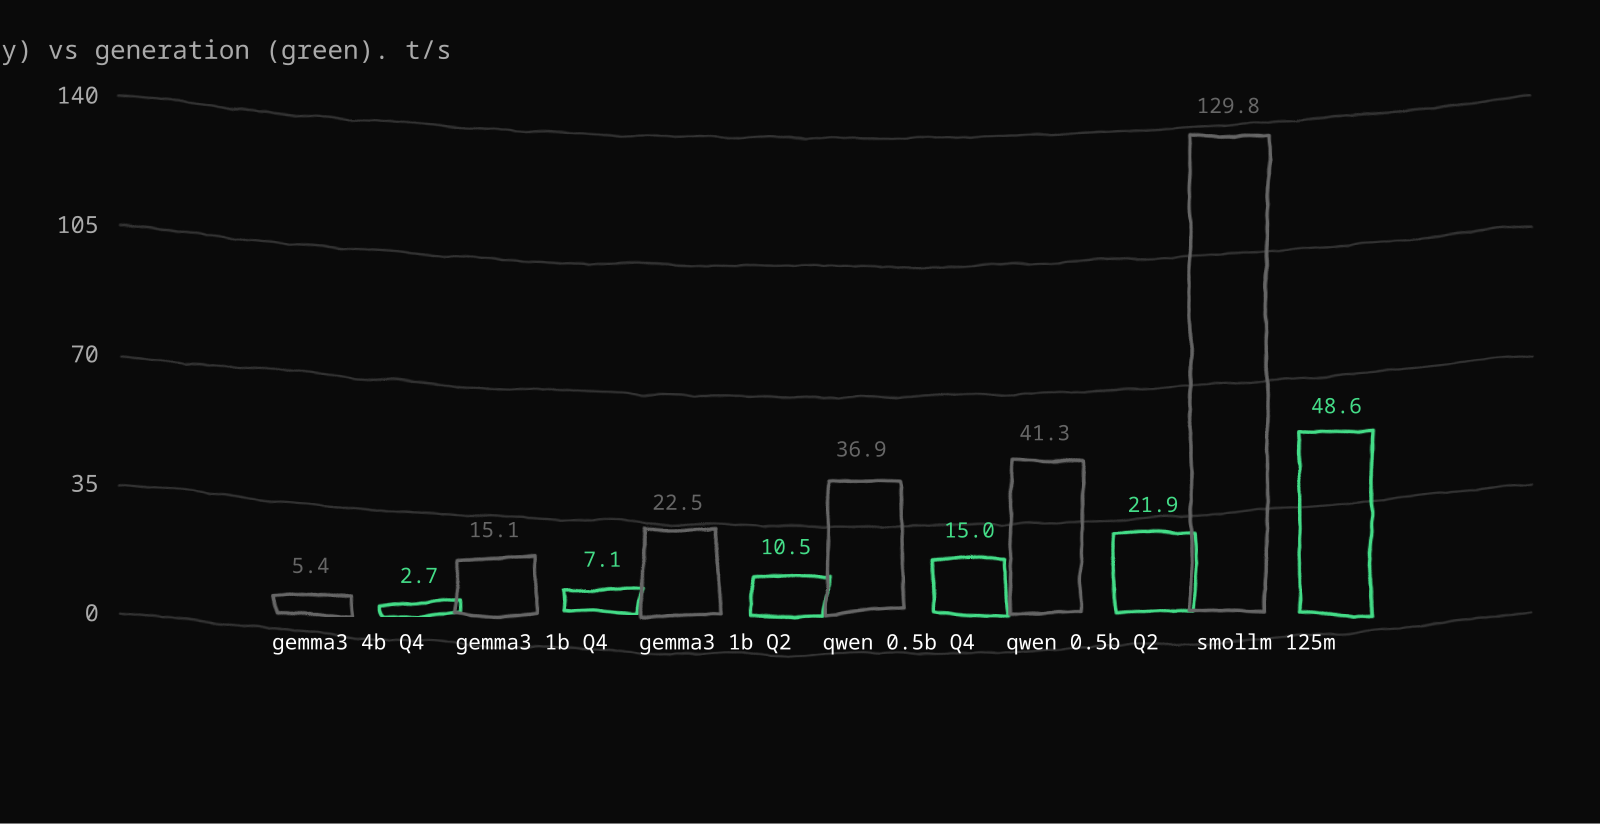 prompt speed in grey, generation speed in green. tokens per second, higher is better
Here's the raw benchmark, straight from my notes. Prompt speed, then generation speed, both in tokens per second.
gemma3 4b Q4:    prompt 5.4  / gen 2.7
gemma3 1b Q4:    prompt 15.1 / gen 7.1
gemma3 1b Q2:    prompt 22.5 / gen 10.5
qwen 0.5b Q4:    prompt 36.9 / gen 15.0
qwen 0.5b Q2:    prompt 41.3 / gen 21.9
smollm 125m Q4:  prompt 129.8 / gen 48.6
So this whole post is really one question. How small can the model go before the output turns to garbage.
speed doesn't slope, it falls off cliffs
Going from 4b down to 1b is roughly a 3x jump in generation speed. Going from 1b down to 0.5b is another 2.5x on top of that. Not a smooth curve, a couple of sharp thresholds where crossing them buys a lot at once.
the second cliff is quantization, not size
Quantization means storing each weight in fewer bits, so a Q2 model has cruder, lower precision weights than the same model at Q4, same parameter count, same architecture. That's a separate lever from shrinking the model itself. Qwen 0.5b at Q2 hits 41 t/s, the same model at Q4 only manages 15. Same chip, same model, just less precise math, and that alone is close to a 3x difference.
(at 2-bit, the model gets stuck. "hello. hello. hello." for 256 tokens straight. that's the reason part 3 exists)
why not just grab the fastest one
If speed was the only thing that mattered, smollm 125m at 130 t/s wins outright, no contest. So why not use it.
Because fixing grammar isn't a speed problem, it's an understanding problem. A 125m model can plausibly complete a sentence one word at a time. It can't reliably hold "who did what to whom" across a full 20 word sentence, it loses track of which noun a pronoun three words later is supposed to point back to. And tracking exactly that is the actual job here. Fast and wrong isn't useful, it's just wrong quickly.
the boring argument, which is the one that actually matters to me
Privacy, latency, and money. Cloud whisper plus a cloud llm means my voice leaves my desk, gets processed somewhere else, and comes back. If the connection hiccups even slightly, my text shows up three seconds late, which defeats the entire point of something meant to feel instant. And I'd be paying monthly for that. Running locally means the models stay warm on my own machine, cost nothing per sentence, and the mic audio never leaves the desk in the first place.
So "why 0.5b" ends up being a three part answer, not one. It has to run on my laptop without pinning every core. It has to be fast enough that the correction feels like it's keeping up with me, not trailing behind. And it actually has to understand grammar well enough to be worth running at all. 0.5b is roughly where those three requirements stop fighting each other.
The trade, it still mangles a sentence here and there. But a repeat penalty in the sampler killed the stuck-in-a-loop echoing, and whisper's transcripts were decent enough going in. Good enough.